Hardware, OS & Infrastructure
Runs Where You Run
kiLM ships as a self-contained stack you host yourself — a single Linux box for a CPU-only trial, an NVIDIA GPU for production inference, or a Kubernetes GPU node-pool at scale. Same images on bare-metal, EKS / GKE / AKS, or fully air-gapped. Pick the tier; we size the rest with you.
Hardware Specifications
Minimum, sustained-performance specifications for serving Small, Medium and Large local LLMs. Treat these as planning floors — we confirm final sizing against your model, context length, concurrency and corpus before you buy.
| Parameter | Small LLM | Medium LLM | Large LLM |
|---|---|---|---|
| Model Class | 3B–8B | 14B–35B | 70B–72B~ |
| Typical Quantization | 4-bit or 8-bit | 4-bit | 4-bit |
| Approx. Model-Weight Size | 2–8 GB | 9–24 GB | 40–55 GB |
| Typical use | Trial, PoC, Small Department, Low Concurrency | Enterprise Production, better Reasoning / Tool Use, Moderate Concurrency | High-Quality Reasoning, Long-Context or Specialist Workloads |
| Processor | 16 physical CPU Cores, 3 GHz+ preferred | 24–32 physical CPU Cores | 48–64 physical CPU Cores per Compute / Data Node |
| Processor features | Modern Server / Workstation x86-64, AVX2; High Memory Bandwidth | Server-Grade x86-64, AVX2/AVX-512 where supported | Dual-Socket or High-Core Server Platform; High Memory Bandwidth and PCIe lane Capacity |
| System RAM | 64 GB recommended; 32 GB absolute Platform floor | 128–256 GB ECC | 256–512 GB ECC per Node |
| GPU | Optional for 3B; strongly recommended for 7B–8B | Required for satisfactory Production Performance | Required |
| Recommended VRAM | 16–24 GB (with GPU) | 32 GB minimum; 48 GB recommended | 80 GB allocatable per Model Replica |
| Example GPU class | NVIDIA L4 24 GB, RTX 4090 24 GB or equivalent | L40S/A6000/RTX 6000-class 48 GB; 32 GB card for constrained 30B serving | A100/H100-class 80 GB or equivalent |
| Number of GPUs | 0–1 | 1 per inference replica | 1×80 GB per replica, or multiple GPUs only with validated tensor parallelism |
| Hot Storage | 1 TB enterprise NVMe SSD | 2–4 TB enterprise NVMe SSD | 4–8 TB NVMe per inference/data node |
| Model-Cache Volume | 250–500 GB NVMe | 500 GB–1 TB NVMe | 1–2 TB NVMe |
| Lake storage | 2 TB usable starting capacity | 4–10 TB usable | 10–50 TB+, Governed by Corpus and Retention |
| Backup Storage | At least 2× Protected Live Data | At least 2× protected live data, off-host | Off-host/off-site immutable backup, sized for retention and restore drills |
| HDD Usage | Cold Backup / Archive only | Cold Backup / Archive only | Cold Tier or Immutable Backup only |
| Network | 1 GbE minimum; 10 GbE preferred | 10 GbE | 25 GbE; 100 GbE for Distributed Inference / Training |
| Power/Cooling | Workstation/Server supply sized for one GPU | Dedicated Server Power and Cooling | Datacenter-grade Redundant Power and Cooling |
| Recommended Topology | One all-in-one Host | Separate GPU inference host and CPU/data-services host | 2+ GPU Replicas plus 3 Fault-Domain-separated Service / Data Nodes |
| Inference Runtime | Ollama or vLLM | vLLM for Evaluation / Production; Ollama for PoC | vLLM with validated Tensor Parallelism and Replica Routing |
| Indicative Workload | Low Concurrency, Shorter Contexts | Moderate Concurrency, 14B–32B Model, Multi-LoRA possible | High-Quality 70B serving, Long Context, High Concurrency or Multiple Models |
Suggested Configurations
Concrete, purchasable starting points. The Medium configuration is our default recommended enterprise starting point; Large is a multi-node architecture, not simply a bigger single server.
| Resource | Small / PoC | Medium / Production | Large / Enterprise (per inference node) |
|---|---|---|---|
| CPU cores | 16 | 24–32 | 48–64 |
| RAM | 64 GB | 128–256 GB ECC | 256–512 GB ECC |
| GPU | 1×24 GB NVIDIA | 1×48 GB NVIDIA | 1×80 GB (2×80 GB only with validated tensor parallelism) |
| Hot storage (NVMe) | 1 TB | 2–4 TB enterprise | 4–8 TB local model/cache |
| Object / backup | 2 TB separate | 4–10 TB | Off-host immutable |
| Network | 10 GbE | 10 GbE | 25 GbE or faster |
A CPU-only Small install is possible, but response latency, VLM processing, embeddings and ingestion throughput will be limited — still provision 64 GB RAM if the full platform stack is enabled.
For better isolation at Medium and above, place vLLM and GPU workers on one GPU node and PostgreSQL, Qdrant, OpenSearch, Temporal and SeaweedFS on a separate CPU/data node.
Large is a topology, not a box: at least two inference replicas, three fault-domain-separated service/data nodes, off-host immutable backup, and N+1 capacity after losing one node. A single machine running several containers is process redundancy, not enterprise HA.
Sizing GPU VRAM Correctly
GPU VRAM is not a simple aggregate — a 48 GB model does not automatically fit on two 24 GB cards. Unless the exact model, quantization and runtime have passed a tensor-parallel benchmark, kiLM sizes the model against the largest single GPU.
Required VRAM =
    quantized model weights
  + KV cache  (context length × concurrent sequences)
  + inference-engine overhead
  + loaded LoRA adapters
  + 20–25% operational headroom
KV-cache use grows with both context length and simultaneous requests, so a 32B model that fits one 8K-context request may fail under several 32K-context requests. A reasonable production assumption is a 24B–35B 4-bit model on a 32 GB card — roughly 18–21 GB of weights, with the remainder for cache and adapters.
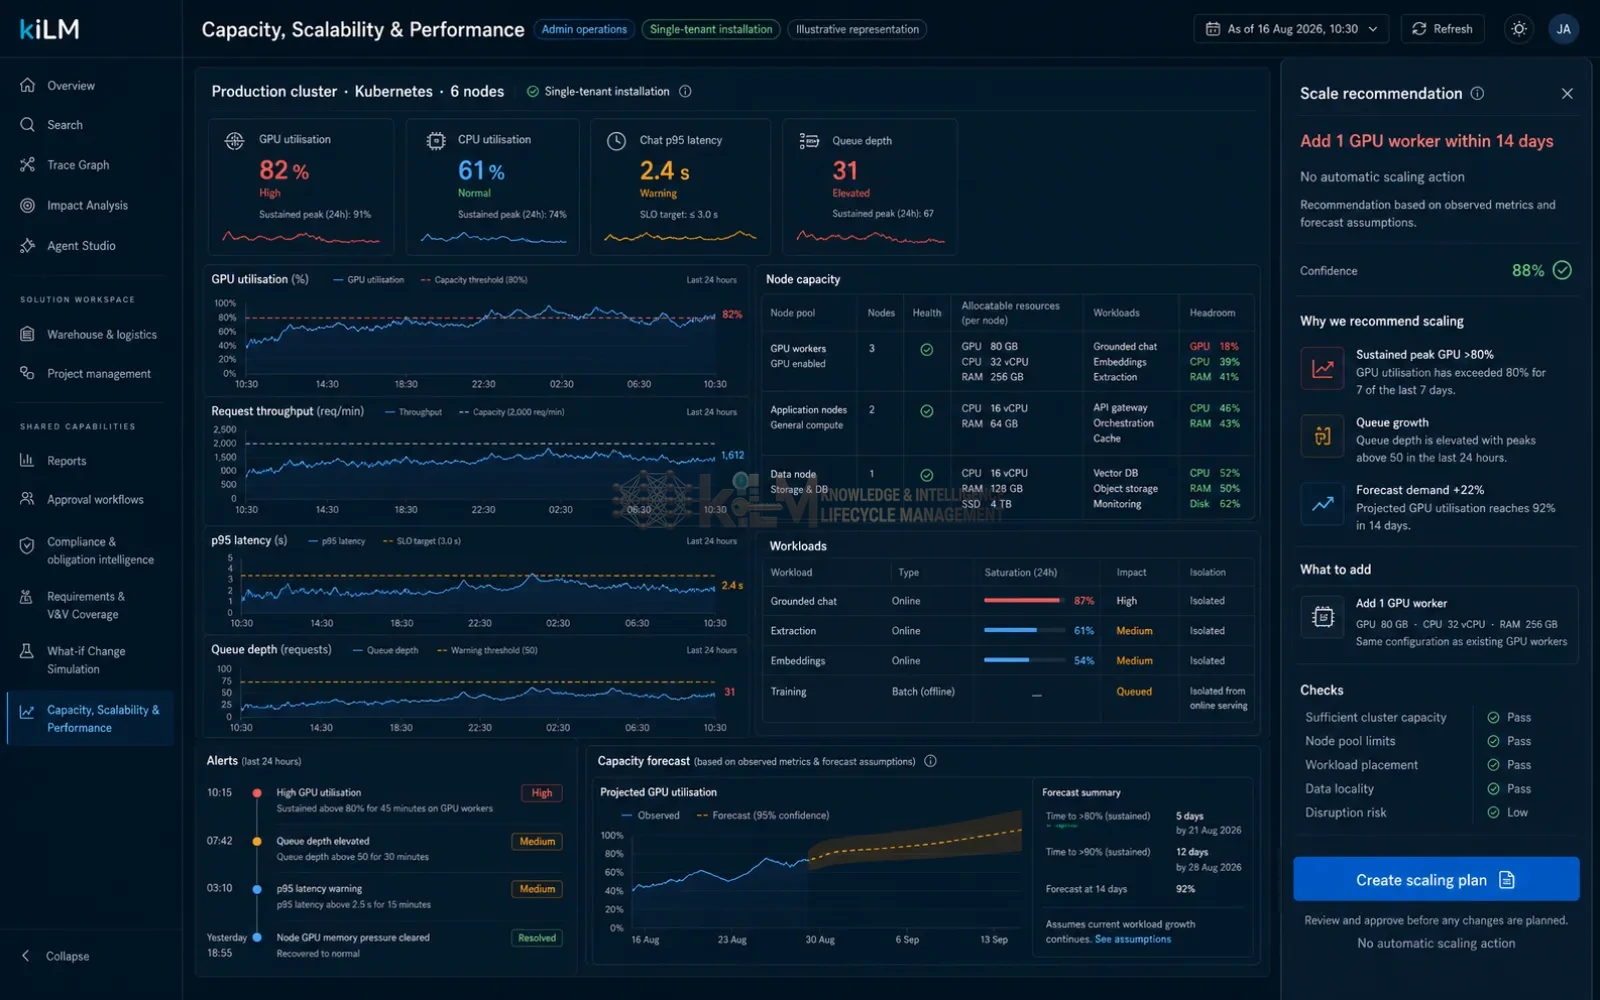
Storage & Training Sizing
Storage is sized against sustained IOPS and throughput, not just capacity. HDDs must not back PostgreSQL, OpenSearch, Qdrant, Temporal, active graph data or model loading — they remain fine for cold archive and backups only.
| Storage class | Read IOPS | Write IOPS | Throughput | Max p99 fsync |
|---|---|---|---|---|
| Trial / PoC hot stores | 10,000 | 5,000 | 200 MB/s | 5 ms |
| Evaluation / Production hot stores | 50,000 | 25,000 | 800 MB/s | 2 ms |
| Production WAL volume | — | 10,000 | 200 MB/s | 1 ms |
| Model / object volume | Throughput-oriented | — | 400 MB/s seq. | — |
| Backup / archive | No strict floor | — | Capacity-oriented | — |
Fine-tuning and distillation need separate sizing — training must not share the production chat GPU, since it can exhaust VRAM and cause unpredictable latency. Indicative training starting points:
| Training workload | Practical starting point |
|---|---|
| 7B–8B LoRA / QLoRA | 1×24 GB GPU; 64–128 GB RAM |
| 14B LoRA / QLoRA | 1×48 GB GPU; 128 GB RAM |
| 30B–35B QLoRA | 1×80 GB GPU; 256 GB RAM |
| 70B QLoRA | Multiple 80 GB GPUs; benchmark exact topology |
| Full-parameter fine-tuning | Dedicated multi-GPU training cluster; outside normal install sizing |
| Distillation | Separate teacher-inference + student-training, or non-production windows |
GPU & Model Dependencies
Beyond the host OS and container runtime, GPU serving and model onboarding carry a few customer-side prerequisites.
GPU software (BYOL)
A compatible NVIDIA host driver, the NVIDIA Container Toolkit, GPU access from Docker/Kubernetes, and — on K8s — the device plugin / GPU Operator (plus DCGM Exporter for telemetry). The NVIDIA driver is a customer/BYOL host dependency, not supplied by kiLM.
Model & AI dependencies
Customer-approved model weights with a completed license review per model; tokenizer, config and quantization files; embedding and reranker models; optional VLM/vision encoders for image search; a model registry with immutable version IDs; and golden evaluation data before promoting a model. Air-gap bundles ship all weights, manifests and license material inside the signed release.
Kubernetes (when scaling out)
Not required for Trial or PoC. Horizontally-scaled production adds a cluster, private registry, CNI/NetworkPolicy, CSI StorageClasses, ingress, GPU node pools, Helm and model-weight PVCs. The focused vLLM inference chart exists today; the full-platform umbrella chart is a larger validation milestone we call out explicitly in proposals.
Internet, Paid-Service & Licensing Posture
A fully packaged air-gap installation needs no internet during normal execution — only internal DNS, time sync, identity services and network access to your own data sources.
When internet is needed
Only when you choose to: pull images or model weights at install time, connect to cloud LLMs or SaaS, use public package/model repositories, send external email/webhook alerts, or use cloud-managed storage, identity or monitoring.
Licensing
Proprietary NVIDIA drivers/tooling are BYOL host dependencies. Every open-weight model's license is evaluated independently. Tools such as fio (GPL-2.0), considered for storage benchmarking, are not bundled without explicit approval.
TLS & secrets
kiLM does not terminate production TLS — front it with a permissively-licensed reverse proxy (Traefik, Caddy or Nginx), bring your own certificates/PKI, and provide secure secret generation and storage. Keycloak handles identity, with enterprise IdP federation where required.
What You Provide
Indicative starting points — not hard floors. Storage and memory scale with corpus size, concurrent users and the Model you choose, and we size against sustained storage performance, not just capacity. We confirm exact sizing for your workload before you buy.
Trial / PoC — CPU
A single Linux x86-64 host with Docker Engine + Compose. Indicatively 8–16 vCPU, 32–64 GB RAM, ~100 GB SSD. No GPU needed; the first CPU answer is slower while the Model warms.
Evaluation / Production — GPU
The above plus one or more NVIDIA GPUs (recent driver + CUDA). VRAM scales with the Model: roughly 16–24 GB for 7–14B-class Models, more for larger ones. NVMe storage recommended for weights + datastores.
OS & Runtime
Any current 64-bit Linux (e.g. Ubuntu 22.04+) with Docker Engine + Compose for the single-host tiers, or a Kubernetes cluster with a GPU node-pool for Eval/Production. Images are amd64.
Hard Dependencies
The non-negotiables the host must provide. Everything else kiLM needs ships inside the containers — these are the few things that live on your side of the line.
Host & OS
64-bit Linux with cgroup v2 (Ubuntu 22.04 / Debian 12 preferred), a synced clock (NTP), working DNS, a host firewall, and persistent volumes for the datastores.
Container Runtime
Docker Engine 24+ and Compose v2.20+ for the single-host tiers (or a Kubernetes cluster with a GPU node-pool for Evaluation / Production).
Deploy Tooling
Python 3.11, make, and jq on the host for the install / maintenance scripts. Containers bundle their own runtimes — these are only for the deploy tooling.
| Area | Dependencies |
|---|---|
| Core platform | Docker / Compose, persistent volumes, host firewall + open ports, DNS, clock sync (NTP), and an external TLS reverse proxy. |
TLS Termination (Yours)
kiLM expects TLS to terminate outside the stack — front production URLs with a reverse proxy such as Traefik, Caddy, or Nginx.
OS-Specific Connectors
The core stack is Linux-container only, but some BYOL engineering-tool connectors run where the tool runs: SOLIDWORKS and AutoCAD sidecars need Windows hosts; CATIA / Creo / NX may need vendor-specific Linux or Windows runtimes — usually on separate customer-side execution nodes.
You Operate, You Secure
A few things stay your responsibility: restrict admin & datastore ports, isolate BYOL sidecars, scope cloud-connector egress, apply a hardware-security baseline (Secure Boot, TPM, full-disk encryption) on production hosts, and hold the Licenses for third-party components (e.g. Ghostscript, Grafana, vendor CAD tooling).
Self-Contained Stack
kiLM bundles everything it needs — no external managed services to procure first. On Kubernetes you can optionally swap in managed datastores; on a single host it all runs in containers.
Bundled Data Plane
Knowledge Graph, vector search, relational + time-series store, object storage and the durable workflow engine all ship inside the deployment — wired together out of the box.
Identity & Observability
Bundled SSO/identity (OIDC + MFA, brokered to your IdP) and metrics/logging dashboards with GPU device-health alerting (Xid, ECC, thermal) — no separate auth or monitoring stack required to get started.
Models
Run the bundled open Models or bring your own. Ollama keeps trials CPU-friendly; vLLM gives GPU throughput at load. Model choice drives the VRAM you need.
Deployment Models
The same container images and feature set everywhere — environment differences live in overlay config, not in the product.
Single Host
Docker Compose on one Linux box (optionally GPU). The fastest path for trials, PoCs and smaller production sites.
Kubernetes
A GPU node-pool on EKS, GKE, AKS or bare-metal. Cloud-specific bits (storage class, ingress, secrets backend) are isolated to per-environment value overlays.
Air-Gapped
No internet connectivity is needed — kiLM runs fully offline.
No runtime internet: images mirrored to your private registry, Model weights pre-staged, egress denied by policy. The signed release bundle installs offline.
Not Sure What You Need?
Tell us your corpus size, user count and whether you need GPU or air-gap, and we will recommend a tier and exact specs.
Ready to size in detail? We walk the full procurement questionnaire — target model and quantization, context length, concurrency, corpus size and ingestion rate, availability target, air-gap vs restricted egress, and backup RPO/RTO — and the complete dependency checklist with you on your quote.